Writing for engineers
Deep-dives into mobile architecture, AI integrations, and engineering craft.
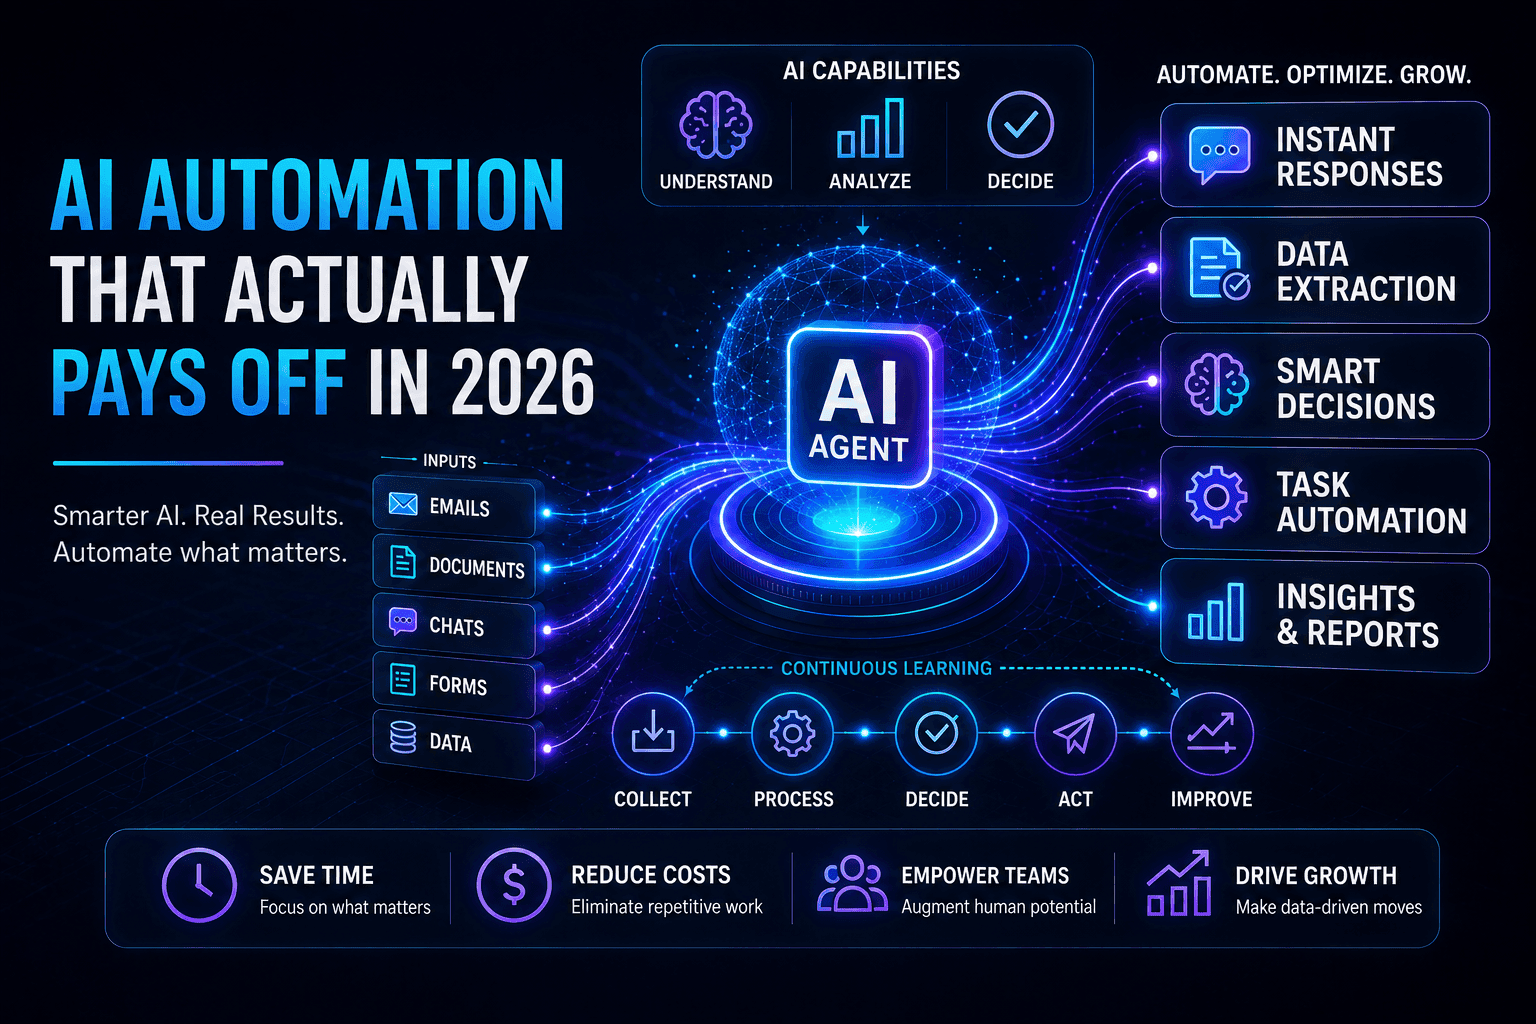
Stop Automating Everything: The Only AI Playbook That Actually Pays Off in 2026
Every business owner has heard "automate it with AI" a hundred times this year. Fewer have seen what that actually means in practice, or what it's worth in doll…
READ ARTICLE →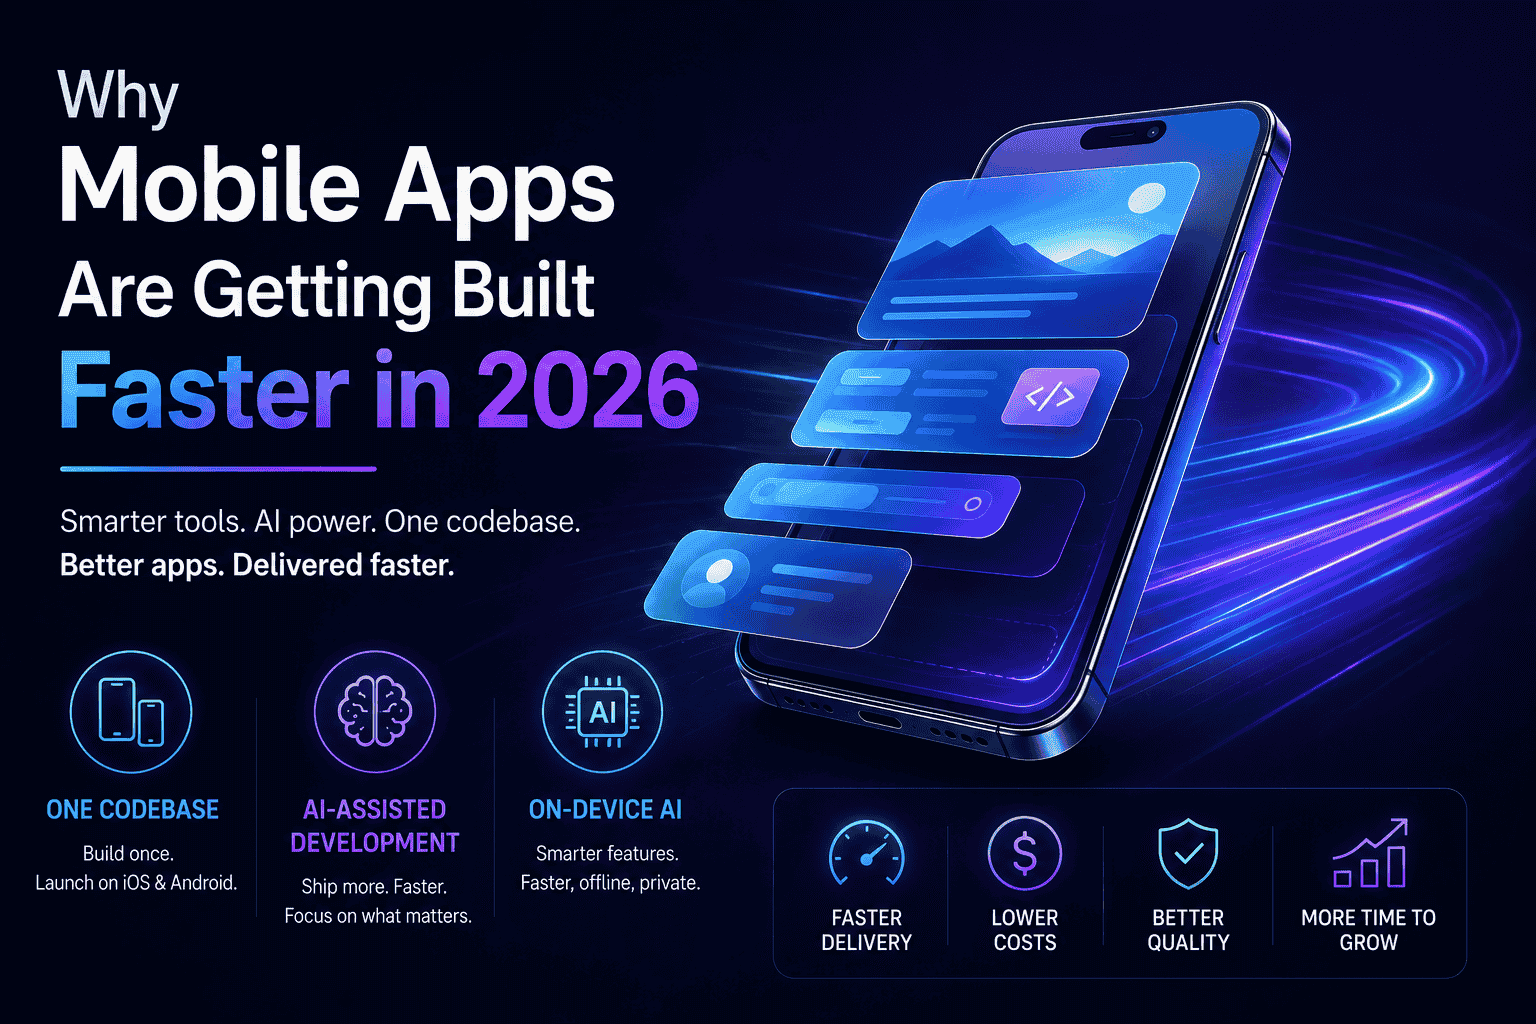
Why Mobile Apps Are Getting Built Faster in 2026 (And How to Make Sure Yours Is One of Them)
If your last mobile app took a year to ship, that's no longer normal — and it's not because developers got smarter overnight. Three practical shifts changed the…
React Native Release Checklist: Store Reviews, OTA, and the Last 10% Before Ship
Shipping a React Native app is easy compared to shipping it again every two weeks without breaking trust. The last 10%—store metadata, rollout strategy, crash m…
Hermes, JSI, and the Latency Budget: React Native Performance From the Trenches
Performance is the one non-functional requirement that users treat as functional. They do not file tickets saying “JS thread congestion”; they say “the app feel…
Scoping React Native Work So Clients Trust Your Estimates (and Come Back)
Nothing erodes trust faster than a surprise invoice—or a scope document that quietly assumed native work was “included.” React Native sits in a fuzzy middle: on…
Shipping AI in Mobile Apps: A Production Playbook for React Native Teams
Everyone wants “AI in the app” until the first battery drain report lands, legal asks where prompts are logged, and your crash-free rate dips because a model bu…
Cross-Platform Mobile in 2026: What Teams Are Actually Shipping
Summary: Flutter, React Native, and Kotlin Multiplatform each have momentum; the winning choice is less about hype and more about your team, modules, and store…
Mobile UX Trends That Double as Accessibility Wins
Summary: Motion, typography, and navigation patterns billed as “modern UX” often align with WCAG-friendly practices—if you implement them deliberately instead o…
On-Device AI Is Rewriting the Mobile Performance Playbook
Summary: Running inference locally cuts latency, improves privacy, and changes how you think about battery, thermals, and model updates on phones and tablets. C…
RAG in Production: The Retrieval Layer Your LLM Roadmap Is Missing
Summary: Retrieval-augmented generation is how most enterprises ground models in their own documents—but naive vector search is only the beginning. RAG sounds s…
From Chatbots to Colleagues: Why Agent Orchestration Is the Next AI Battleground
Summary: Single-shot prompts are giving way to coordinated agents that plan, call tools, and recover from errors. Here is what that shift means for product and…